Retrieval-augmented generation (RAG) makes enterprise AI development more reliable by having a language model fetch relevant, approved company documents before it answers. The model grounds its response in current sources instead of relying only on training data, and it can cite them. That cuts hallucinations, keeps answers up to date, and makes outputs auditable.
Most enterprise AI pilots don’t stall because the model is weak. They stall because a general-purpose large language model (LLM) doesn’t know the business, yet answers confidently anyway.
Gartner predicted that at least 30% of generative AI projects would be abandoned after proof of concept by the end of 2025, citing poor data quality and unclear business value among the causes. For teams doing AI powered app development, reliability is now the main barrier between a demo and production.
What is retrieval-augmented generation (RAG)?
RAG is an architecture that pairs a search step with a large language model, so the model answers from retrieved documents rather than from memory alone. Facebook AI Research introduced it in 2020 [SOURCE: original RAG paper, Lewis et al., 2020].
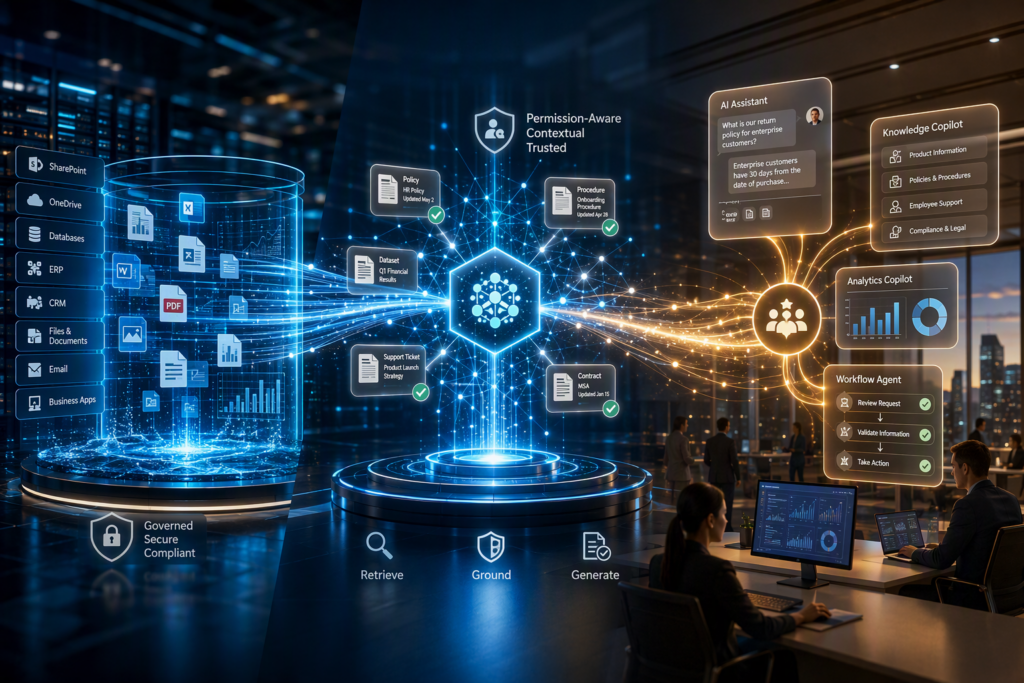
A basic RAG pipeline has five stages:
- Ingest: Collect documents from wikis, ticketing systems, and contract repositories.
- Chunk and embed: Split documents into passages and convert them into vector embeddings. A vector embedding is a numerical representation of text that captures its meaning, so similar passages sit close together.
- Retrieve: When a user asks a question, search a vector database, often alongside a keyword index, for the most relevant passages.
- Generate: Pass those passages to the LLM with instructions to answer only from that context.
- Cite and log: Return source references with the answer and log the exchange for review.
Why do enterprises need RAG instead of fine-tuning alone?
Enterprises need RAG because most business knowledge changes too often to be built into a model’s weights. Fine-tuning shapes behavior; RAG supplies current facts.
| Factor | Prompt-only LLM | Fine-tuned LLM | RAG |
| Knowledge freshness | Fixed at training cutoff | Fixed at last training run | Updated when the index refreshes |
| Source citations | No | No | Yes |
| Access control | None | None | Can enforce document-level permissions |
| Cost to update | Low | High (retraining) | Low to moderate (re-indexing) |
| Best for | General tasks | Tone, format, specialized behavior | Fact-based answers from company data |
Many production enterprise AI development projects use both.
How RAG makes AI powered app development more reliable
RAG improves reliability by limiting what the model can say and making every answer traceable. Typical benefits:
- Fewer hallucinations: Answers rest on retrieved text, and the model can decline when nothing relevant turns up.
- Auditability: Citations let reviewers verify claims, which matters in legal, healthcare, and financial services.
- Permission-aware answers: Retrieval can respect existing access controls, so employees only get answers drawn from documents they’re allowed to read.
RAG doesn’t eliminate errors. A 2024 Stanford study found that RAG-based legal research tools still hallucinated on roughly 17% to 33% of queries [STAT – verify source]. Retrieval quality puts a ceiling on answer quality.
Common challenges in enterprise RAG projects
Most RAG failures come from data and retrieval, not from the language model. These problems show up most often in real deployments:
- Poor source data. Duplicated, outdated, or contradictory documents produce confident wrong answers. Gartner reported that 63% of organizations either lack AI-ready data management practices or aren’t sure they have them [STAT – verify source].
- Naive chunking. Fixed-length splits break tables and separate clauses from their conditions.
- Vector-only search. Semantic search can miss exact terms such as part numbers or policy IDs. Hybrid search, which combines keyword and vector retrieval, usually does better.
- No evaluation set. Without a benchmark, teams can’t tell whether a change helped.
A typical case: an HR assistant quotes a three-year-old leave policy because both versions were indexed. The model worked as designed; retrieval failed.
Best practices for production-ready enterprise AI development
Start with a narrow, high-value use case, such as internal IT support or contract clause lookup. Broad “ask anything” assistants are harder to evaluate.
Before tuning anything, build a test set of 100–200 real questions with expert-verified answers. Track retrieval precision, answer faithfulness, and citation accuracy separately.
Add reranking, metadata filters, and freshness rules so current documents outrank archived ones. Align controls with a recognized framework such as the NIST AI Risk Management Framework.
As organizations adopt AI agents, RAG becomes their knowledge layer, and weak retrieval turns into wrong actions, not just wrong answers.
Key Takeaways
- RAG grounds LLM answers in approved company documents, making enterprise AI development more accurate and auditable.
- RAG supplies current facts; fine-tuning shapes behavior. Many systems use both.
- Most RAG failures come from poor data, weak chunking, and missing evaluation, not from the model.
- A tested question set and permission-aware retrieval are baseline requirements for production.
Conclusion
RAG has become the default architecture for enterprise AI development because it links model fluency to business facts. The next competitive gap won’t be about which LLM a company picks. It will be about how well each organization curates, governs, and evaluates the knowledge its AI applications retrieve.
FAQ
Does RAG eliminate AI hallucinations? No, but it reduces them significantly. RAG grounds answers in retrieved documents, so the model has less room to invent facts. Hallucinations can still happen when retrieval returns irrelevant or outdated passages, or when the model misreads context. Evaluation sets, citations, and answer-faithfulness checks help catch the errors that remain.
What is the difference between RAG and a standard AI chatbot? A standard AI chatbot answers from what its model learned during training, which may be outdated or generic. A RAG-based chatbot first searches an organization’s own documents and then answers from those results, usually with citations. That makes RAG better for company-specific questions about policies, products, contracts, or internal procedures.
What data sources can a RAG system use? RAG systems can use almost any text-based source: document management systems, wikis, PDFs, ticketing platforms, CRM notes, databases, and email archives. Structured data can be included through database queries or converted summaries. The key requirement is clean, current, well-permissioned content, since the system can only be as accurate as its sources.
Is RAG secure enough for sensitive enterprise data? It can be, when designed carefully. Secure RAG deployments enforce document-level access controls during retrieval, encrypt data at rest and in transit, log every query, and may use privately hosted models. The biggest risk is indexing sensitive documents without permission filters, which lets users retrieve content they shouldn’t see.
What drives the cost of building a RAG application? The main cost drivers are data preparation, vector database hosting, LLM usage per query, and ongoing evaluation. Data cleanup is often the largest and most underestimated expense. Costs rise with document volume, query traffic, and accuracy requirements. Starting with a narrow use case keeps spending predictable while the team learns what works.